Every software vendor now says they use AI. Most of them mean that each developer has an assistant in the editor. That is a productivity tool, and it is a good one. It is not a methodology, and it does not answer the questions a buyer still has to ask before signing off: are we building the right thing, is it built on a foundation that will hold, will it keep up as the business changes, and how do we know it is correct without reading every line?
This post explains how we answer those questions at Diffco, and why the answer produces software that arrives faster and passes an audit. We call the method Production-Ready AI Engineering. Inside the company we just call it how we build.
Code is the cheap part now
Two years ago the constraint on a software project was how fast people could write code. That constraint is gone. An agent can produce a feature, its tests, and its documentation in the time it takes to read the ticket.
What that changes is where the risk lives. When code is cheap, the expensive mistakes are the ones made before any code exists: solving the wrong problem first, choosing a foundation that will not hold at ten times the users, betting on a vendor that will not be there in two years, or building something that should have been bought. Fast code gets you to the wrong place sooner.
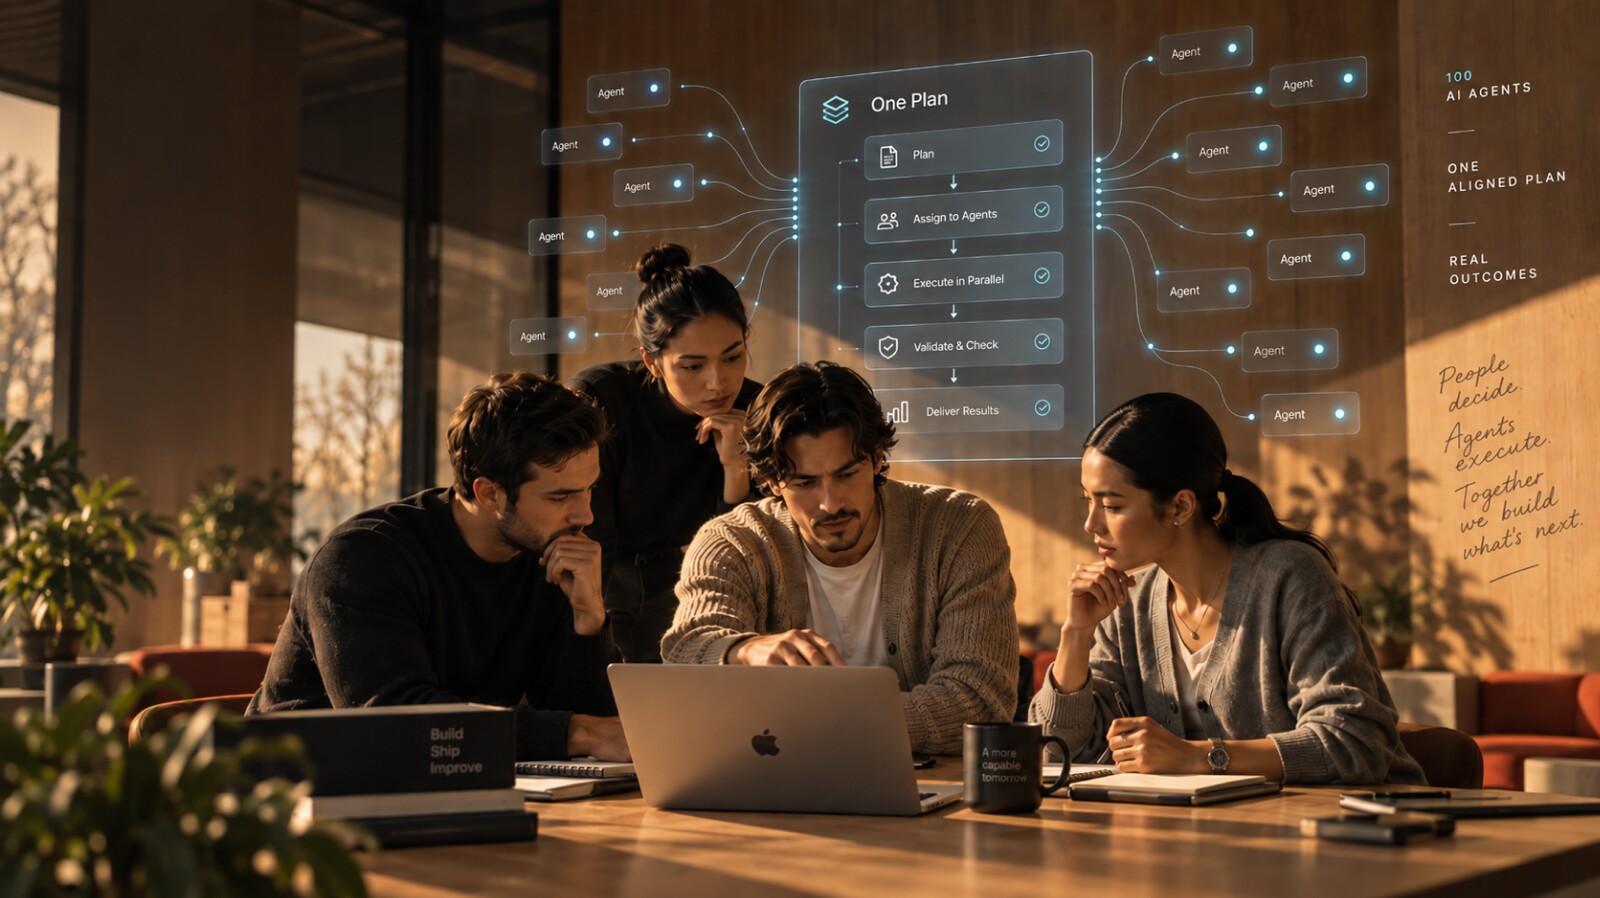
So the method starts with a claim about people, not tools. Senior engineers, architects, and product managers decide what to build and how. Agents build it. And a plan, kept alive and checked by software, sits between the two so that a hundred agents working at once produce one coherent product rather than a hundred plausible fragments.
What a living plan actually is
“Plan” is a deliberately plain word for something quite specific. On a Diffco project the plan is a connected set of small, addressable items kept in plain files beside the code: the goals the software serves, the rules it must never break, what each part must do, how each part works, and the architecture decisions with their alternatives. Each item has a permanent label. Every requirement names the goal it serves. Every technical specification names the requirement it fulfills. Every piece of code names the specification it implements.
Three things follow from that structure, and they are what make the method work at speed.
First, “why does this exist?” is a one-step question for any piece of the product. Six months after launch, when someone asks why the invoice export leaves out customer email addresses, the answer is one hop away: a data-protection rule, the decision that applied it, the person who made it, and the date.
Second, change becomes computable. When a requirement changes, everything that depended on it is flagged the same day: what needs new work, what has been invalidated, and what looks untouched but now needs a second look. You approve that picture before anything is built. This is the difference between software that absorbs change and software that quietly breaks somewhere else.
Third, the plan can be checked by a program. Every time work is saved, a checker runs. A requirement altered without an approving decision, a piece of code that no longer matches what it claims to implement, a reference to something that no longer exists: the change does not go through. The rule is enforced by software, not by a memo, so it is enforced every time.
The platform: what a hundred agents need that one assistant does not
An assistant helping one developer can rely on the developer to hold the context. A hundred agents working in parallel cannot. Left alone, they drift: one invents a data model the other has already replaced, one writes a test that passes because it seeded the state it was supposed to reach, one “fixes” a requirement to make its task easier.
Our delivery platform exists to stop that. It runs on top of the leading coding agents, Claude Code and OpenAI Codex, and it does four things for every agent session.
It puts the plan in front of the agent before it starts: the goals, the rules, the decision log, and the compliance requirements that apply to the area being touched. It resolves every label the agent mentions into its full definition, so context is never a matter of what the agent happened to read. It refuses an edit to a specification the agent has not loaded in that session, and it refuses any change to a goal, requirement, or rule that does not carry a named person’s decision. And it checks everything the agent produces against the plan the moment it is saved.
Two further behaviors matter over a long project. The platform learns your project: ask for the same thing twice and it becomes a project rule every agent follows from then on, while a passing preference never hardens into a constraint. And it is model-independent. The plan and the checks do not care which model wrote the code, so when a better model arrives we adopt it without changing how your project runs.
Any team can rent a hundred agents today. The difference is whether they work inside one plan or in a hundred chat windows.
Why it is faster
Speed here does not come from typing faster. It comes from removing the things that make projects slow.
Parallel work under one plan. Features, tests, reviews, and documentation are produced concurrently by agents that all read the same source of truth, and they do not stop when the office closes. A senior engineer’s day goes into decisions and review rather than implementation.
Prototype before build. Within days of Discovery, a whole flow of your product is real, clickable screens with real content, in the order your users will meet them. You change your mind while it is cheap. Anything nobody has decided yet is marked on the screen, so it becomes a decision in week one instead of a surprise in month five.
Contested decisions get built, not debated. When two stakeholders want two different behaviors, the agents build both versions in hours and the argument is settled by watching them. We bring the evidence; you make the call.
Change costs what it should. Small changes just get made. Larger ones arrive with their full impact already computed, so nobody spends a week discovering what broke. The rework that usually appears months later, from a requirement that changed in March and was noticed in October, does not appear.
A typical shape: a mid-sized finance workflow, Discovery in under two weeks, a clickable walkthrough in the first week of build, a first working release a few weeks later. Not because anyone hurried, but because nothing waited.
Why it is enterprise-ready
Speed without control is how regulated companies end up with software nobody can explain to an auditor. The same structure that makes the method fast is what makes it defensible.
Traceability is a by-product, not a project. Each requirement is already linked to the code and tests that satisfy it, each decision already carries a name and a date, and each architecture choice already has its alternatives recorded. The evidence design-control and change-management reviews ask for is produced as we build.
Compliance goes into the plan first. Security and regulatory requirements, whether SOC 2, HIPAA, PCI DSS, or your own policies, become rules every agent reads before it starts and the checker enforces on every change. That includes which models may see your code and what data the agents may touch, agreed in Discovery and enforced as project rules rather than trusted to habit.
A person watches it work. For each important thing your users need to do, we write down what “working” means before the code exists, and you agree to it. At release, that task is demonstrated live on the real product and a person signs off against that standard. Passing tests are necessary. They are not the same thing as a person watching your software do the job. The sign-off is attached to the version demonstrated, so when the code underneath changes, the demonstration comes back to you instead of quietly aging.
Nothing is decided by a model. No agent can change a goal, a requirement, or a rule on its own. When you say no to something, the reason is kept as a constraint, so nobody proposes it again nine months later. Firm decisions are never quietly traded away.
A typical shape here: a healthcare product where a data-handling rule is written once in Discovery, and from that point every agent that touches patient data sees the rule before it starts and cannot save a change that violates it. The compliance conversation at release is a reading of the log, not a hunt.
What we do not claim
The method is heavier than a throwaway prototype or a two-week experiment needs, and we will say so; for those we run something lighter. It cannot find a requirement nobody ever names, which is why Discovery gets the most attention rather than the least. And it does not make a product compliant by itself. Your compliance program does that. What the method gives that program is the traceability it runs on.
The one idea to take away
AI writes the code. People decide what to build, and people decide whether it works. Everything else in the method exists to make those two human decisions cheap, well-informed, and on record, while a hundred agents do the rest around the clock.
If you want to see how your current system would answer the four questions at the top of this post, start with a free architecture review. We map your goals, your technology, and your existing code onto the plan and show you what it surfaces, which is usually a few things nobody had written down.