The request usually arrives worded like a procurement task: “We’re rolling out Claude Code. Can you help us implement it?” What the person asking often has in mind is a training day, a licensing conversation and perhaps a shared prompt library. I want to explain why none of that is the implementation, what actually is, and how we run it — because we run the same setup on our own client work every day, and we’ve watched what happens to teams that skip it.
The spike, then the dip
Every team that adopts Claude Code by handing out licenses gets the same curve. Output jumps in the first weeks. Then review queues grow, the same bug appears in two places, and a senior engineer quietly becomes the full-time reviewer of everyone else’s generated code. The tool isn’t the problem. The problem is that nothing tells a hundred agents what the product is for, what must never change, and what was already decided.
The specific failures are predictable enough to list. Every session starts from zero: there’s no plan the agent can read, no rules in the repository, no record of past decisions, so each engineer gets a different Claude and it forgets by Tuesday. Agents change things people decided — a requirement quietly rewritten, a constraint dropped, a “no” from March re-proposed in October, because nothing stopped them. Nobody can see where the project stands, since progress lives in a hundred conversations and finished, blocked and broken look identical from outside. Large diffs get thin review, waved through because “the tests passed” when nobody wrote down what working means. Secrets and data end up where they shouldn’t: credentials in prompts, production data as fixtures, no rule about which models may see the code. And the gains stay with two people — a couple of engineers get three times faster, the rest get frustrated, and without deliberate enablement it never spreads.
None of these is a Claude Code bug. They’re what happens when a capable agent is dropped into a codebase with no plan around it.
What “implementation” actually installs
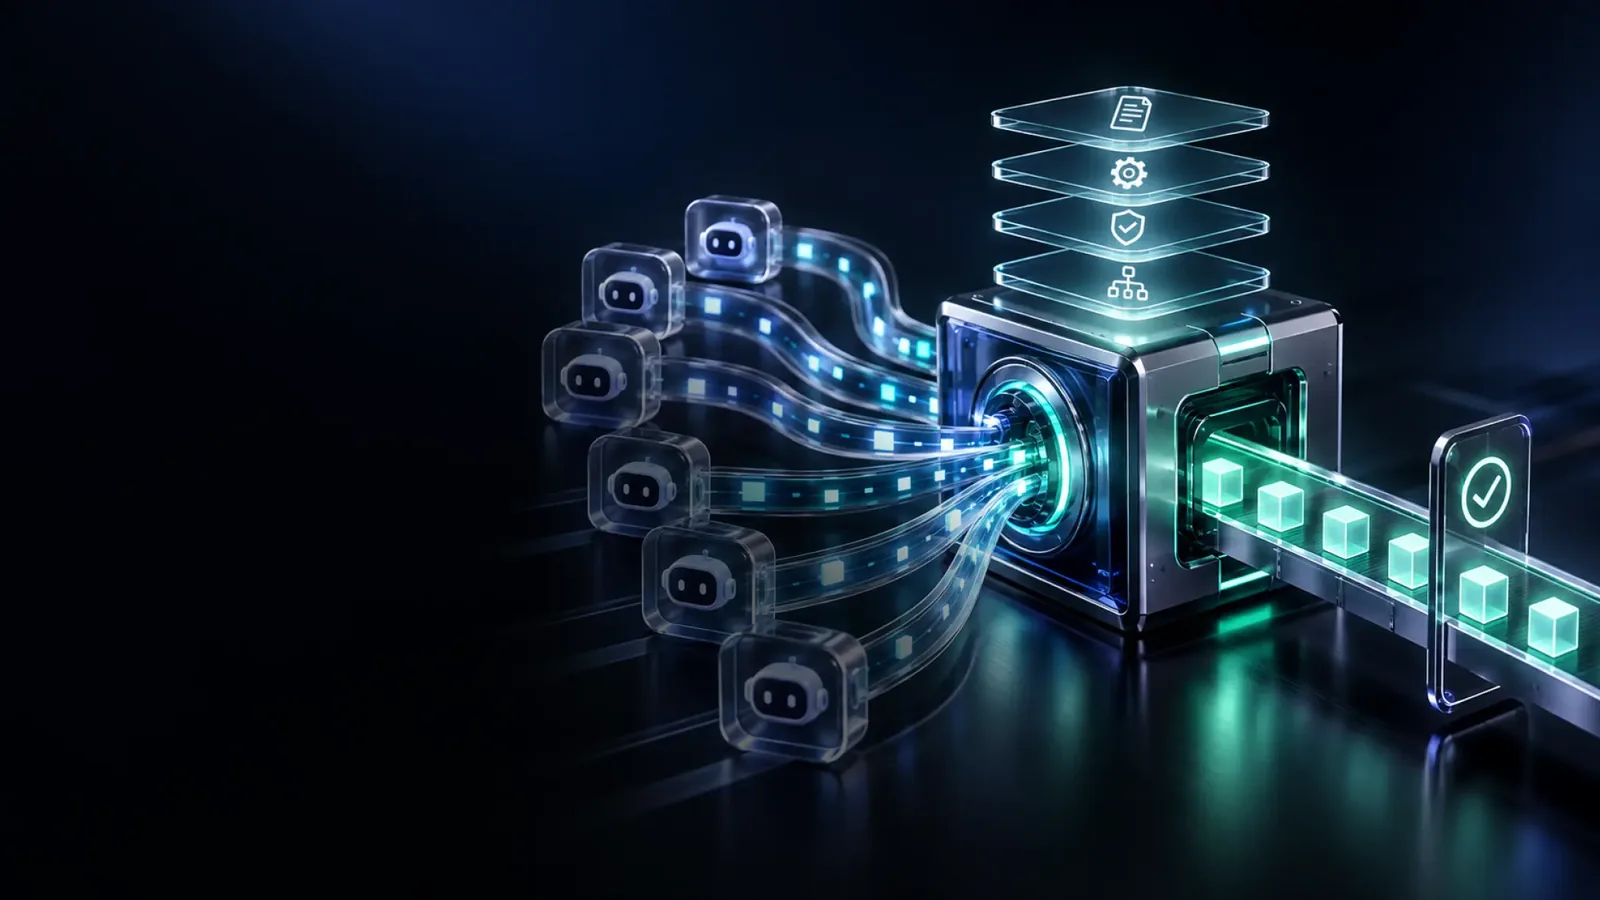
An implementation partner’s job is to put five things in front of every agent before it writes a line, in your repository, on your backlog. All five are plain files you own.
The plan. Your product’s goals, the requirements that serve them, and the code that fulfils those requirements, connected so that every piece of code names the part of the plan it exists for. This is the artifact that means an agent starting on Tuesday knows what was decided on Monday. It’s drafted from everything you already have — codebase, docs, tickets, the architecture diagram someone made two years ago — and agreed with you before anything else happens.
The rules. The constraints that must never be broken: what the system may not do, which boundaries hold, which decisions are firm. Rules are read by every agent before it starts. The distinction we insist on is between firm decisions and passing preferences: the first are never quietly traded away, the second never block progress. When you ask for the same thing twice, it becomes a rule from then on, so the system learns your project rather than software in general.
A check on every save. Every time work is saved, it’s checked against the plan and the rules. A change that breaks the plan doesn’t go through. This is where most of the quality dip disappears: issues surface at the moment they’re cheapest to fix, not in a review a week later, and the reviewer’s job shrinks from “read everything” to “decide the things only a person can decide.”
The decision log. A dated record of who approved what, and what it affected. This matters to engineering leads for obvious reasons and to regulated buyers for a different one — it’s the record due diligence and auditors ask for, produced along the way instead of assembled in a panic.
The acceptance standard. For each key user task, what “working” means is written down before the code exists, and before release a person watches that task work on the real product and signs off against that standard. Not a test log. A person, a real screen, a named sign-off.
With those in place, the agents stop being a hundred chat windows and become throughput inside a structure. That’s the implementation. The licenses are incidental.
How a two-week setup sprint runs
We do this as a fixed-scope engagement with your engineers, on your repository, against your real backlog. It is deliberately not a training course.
Days one to three go to the plan. We draft it from what you already have and sit with your leads until it’s agreed — usually the first place where the exercise surfaces decisions nobody had written down. Then the rules and the check go into the repository, and we point agents at actual backlog items rather than exercises. From there your engineers direct the agents with us alongside: they make decisions and read reports, the agents do the day-to-day writing, and we adjust the rules as real work reveals what’s missing. The sprint ends with a re-measured baseline — cycle time, review load, defect rate, whatever you were measuring before — and a written operating model your team owns. The price is fixed.
Your people don’t learn a new tool. That’s a design goal, not a side effect. The plan is plain files that live beside your code, and the reporting is one page that shows what’s finished, what’s waiting on your decision, and what needs a second look.
RedTrack, whose attribution platform tracks ad spend for more than a thousand performance-marketing teams, asked us to set up AI-native development across its engineering organization — methodology, agentic workflows, tooling and practices. That engagement is the template for the sprint, and it’s the reason the sprint is two weeks rather than a slide deck.
The security questions to ask first
When agents write most of the code, three questions decide whether the setup is safe, and I’d ask them of any partner before signing.
Which models may see our code, and where does it go? Your answer becomes a rule every agent reads and the check enforces — including model access, data residency and which repositories are in scope at all.
What data can the agents touch? Secrets never enter prompts. Production data is never used as fixtures. The check catches both, and the rule is yours to tighten.
Who is accountable for a change? Every change that matters carries a named person and a date. The decision log is the answer to “who approved this” six months later, and it exists from the first week.
Data-handling terms are agreed in writing before work starts. If a partner can’t show you where these rules live in the repository, they aren’t implementing anything; they’re running a workshop.
Why the plan can’t depend on one model
We build on Claude Code, and it’s the agent we reach for first on long, context-heavy refactors and deeply agentic systems. We also run OpenAI Codex and Cursor inside the same plan. The reason is architectural, not diplomatic: the plan, the rules and the check are yours and model-independent, so a better model is adopted as a configuration change, not a re-platforming. Codex reads the repository’s AGENTS.md conventions; Claude Code reads its own; the plan underneath is the same file set.
Which agent a team should standardize on is usually decided by constraints rather than preference — existing enterprise agreements, data-residency terms, what the team already knows, and the shape of the work. Many small, well-scoped tasks that benefit from parallel cloud execution point one way; a single long refactor points another. We’ll recommend against our own preference when your situation calls for it.
When not to do this
Some codebases aren’t ready: no tests, no boundaries, a deployment process that lives in one person’s head. Bring the code under the plan first, without rewriting it — the checks apply to new work from day one and older areas come under the plan as you touch them — and the sprint follows. Some compliance regimes need the data-handling rules settled before any agent touches anything, which is a legal conversation, not an engineering one. And some teams need a two-week experiment, not an operating model; if that’s you, we’ll say so and run something lighter that ships fast. We tell clients when AI is the wrong tool. It’s the cheapest sentence we say.
My honest take
The question I’d put to any implementation partner, including us, is simple: show me the plan you’d write for our product, the check that runs on every save, and the sign-off record from your last release. If they can put those three things on a screen, they’ve done this. If they talk about prompt engineering and adoption curves instead, they’re selling training.
A personal aside: the moment I watch for in every sprint is when a senior engineer stops reading diffs line by line and starts reading the one-page report instead. It takes about a week. After that they get their evenings back, and the agents get a director instead of a proofreader.
If you’re deciding how to roll Claude Code out across a team — or you’ve already handed out the licenses and the dip has arrived — start with a free architecture review. We’ll map your goals, your code and how your team uses AI today onto the plan, and show you what nobody had written down.