REDTRACK × DIFFCO
RedTrack: Making an Ad-Tech Platform AI-Native
Diffco diagnosed why a well-tooled engineering organisation was not compounding, then installed the operating practice around the answer — specification-driven development, documentation on hard CI/CD gates, and agent workspaces that leave evidence behind.
At a glance
Development acceleration
- Before
Baseline (AI-assisted development)- After
- 20X+ on AI-native workstreams
Ticket to production
- Before
2–5 weeks- After
- Minutes or hours
Engineers using AI daily
- Before
Only 30% of the team used AI to accelerate development- After
- 100% of the development and product team; 100+ AI agents running 24/7
Human role on AI-native tasks
- Before
Implementer- After
- Reviewer / harness engineer
Background
The client
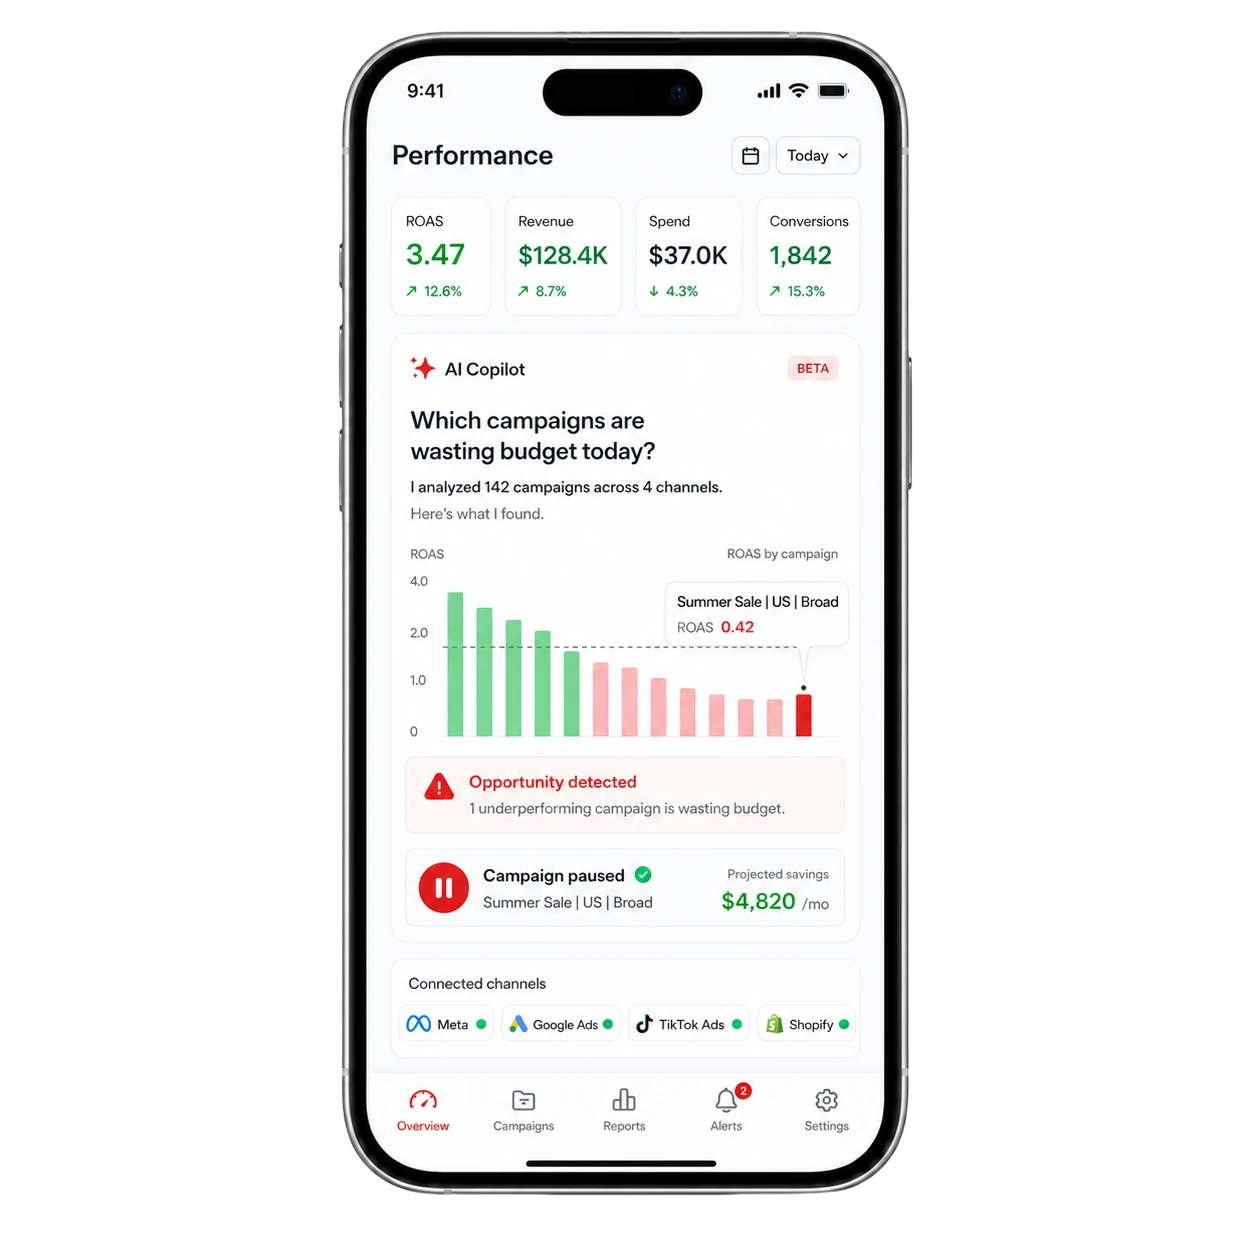
RedTrack is an all-in-one performance marketing analytics SaaS platform: server-side ad tracking, cross-channel attribution, and media-buying automation for e-commerce brands, affiliates, and agencies. The platform serves 5,000+ active media buyers, tracked more than one billion conversions in 2025, and integrates with 200+ ad platforms and tools.
Under the hood the ingestion layer handles thousands of requests per second and the analytical layer orders of magnitude more queries per minute, across a polyglot stack — Go on the high-throughput data path, TypeScript in the product, Python for AI and integration work — with data spread over ClickHouse, ScyllaDB, MongoDB and Elasticsearch. Dozens of services, hundreds of thousands of lines, years of production history.
The engineering team is distributed and remote-first, with technical leadership concentrated in a small number of very senior people.
The problem
The challenge
The founder’s ambition was clear: make the engineering practice AI-native across the whole product, not in isolated pockets. The board had signed off and the team was ready.
And the team was ahead of most of the market on tooling. Several engineers used Claude Code daily. They had built a custom orchestration service that ran it inside CI with per-task budgets and structured outputs. They had layered context files across a subset of repositories.
What they did not have was a return proportional to that investment: only a fraction of the team used AI day to day, monthly AI spend was modest, and the infrastructure was scaffolded while the yield stayed uncaptured.
The question they brought to Diffco was the right one:
We have the tools — why isn’t the transformation happening?
Process
Discovery: the bottleneck was not where everyone thought
We started with roughly a month of Discovery — structured working sessions with leadership, deep reads of the codebase, walkthroughs of in-flight tickets, and calibration against the team’s own materials about their state. Three findings reshaped the engagement. Discovery closed with a written diagnosis, a proposed sequencing, and a memo to the founder on the trade-offs. The direction was confirmed. The shape of the work changed.
The tooling was ahead; the practices were behind
The orchestration service, the context files, the CI integration — all of it was advanced. The operating practices around that infrastructure had not matured to match. Nobody had defined what “done” meant for an agent, what happened when one failed, or who owned closing the gap.
The bottleneck was context, not code generation
Tickets took two to five weeks to reach production not because implementation was hard, but because the context required to do the work — domain knowledge, architectural constraints, decisions embedded in earlier features — lived in a few people’s heads. Every ticket paid the cost of reassembling it: developer to team lead, lead to the stale spec, spec to the person who remembered the spec, then to the code. AI agents hit exactly the same wall for exactly the same reason. They were missing what a new hire is missing.
The team had already designed the right architecture — and paused it for the wrong reason
Technical leadership walked us through a multi-agent pipeline they had designed but not finished: requirements through implementation, human validation at each gate. It was substantially the architecture we would have proposed. They had shelved it because they lacked the documentation depth to feed the analyst agents, and pivoted to code generation instead. Discovery made the sequencing error visible: documentation first, code generation second.
Implementation
What we installed
Two workstreams proceeded in parallel from day one.
The operational foundation
Cloud-based AI development environments — Claude Code running in isolated per-task workspaces, lifecycle managed by the orchestration platform. Consolidation of the multi-repo codebase into a unified working structure so agents could see the whole system when needed. A shared context system: root-level project instructions, a specifications folder as the source of truth, and skill libraries for recurring behaviours. Task lifecycles that ran to completion in isolation and left persistent artifacts, so failures could be investigated after the environment was gone.
The methodological foundation
Specification-driven development as the operating principle, documentation living next to the code with hard CI/CD gates, and the continuous-improvement discipline most teams skip: when an agent falls short, the fix goes into the context, the instructions or the harness — never into patching the individual output by hand. That is what turns improvement from a plateau into a compounding curve.
None of the methodology is novel. What is different is installing it as an operating system rather than running it as a demo.


Outcomes
Results
20X+ acceleration on AI-native workstreams, measured against RedTrack’s previous AI-assisted baseline.
On internal projects — an HR system, an internal metrics dashboard, integration utilities — agents now run the full development cycle: pick up the Jira ticket, make the changes, run the tests, open the pull request. Engineers review and merge.
Structural refactoring moved to AI-native execution within weeks.
JavaScript-to-TypeScript migrations, library upgrades, renames — anything describable as “transform this pattern to that pattern across this scope” runs through the orchestration service cleanly and consistently.
Ticket-to-production time in the transformed parts of the system went from 2–5 weeks to hours or minutes depending on the type of task.
AI adoption moved from 30% to 100% of the team: from using AI to accelerate development to working AI-native daily.
Onboarding got faster as a side effect.
New engineers entering transformed areas of the codebase reached productive contribution meaningfully sooner — not because AI did their work, but because the context they needed was captured, structured, and readable.
The bottleneck moved upstream — which is what progress looks like.
The constraint is no longer “the developer takes two weeks to build this.” It is “the specification has to be good enough for an agent to build it.”